You ask for help exploring an idea.
The tool assumes you want to implement it immediately. It asks about the architecture. You explain that you are still researching. It asks for implementation criteria. You correct it again.
The idea is still waiting. The conversation already contains an entire project you never asked for.
A hypothetical scene. Maybe your subject was something else. The path may feel familiar.
When the assumption becomes the subject
A question can help a great deal. The problem begins when it carries a conclusion that has not yet been agreed upon.
You reply in order to undo the conclusion. The tool interprets that reply within the same conclusion. Now it needs another question. Then another.
With each turn, the history gains material about the wrong path. The original task takes up a few lines; the discussion to recover the task takes up pages.
In this post, we call this context poisoning: a cycle in which interpretations introduced by the model come to steer the conversation, making it harder to revise those very interpretations.
We are not talking here about an external attack. We are talking about a collaboration that gradually gets stuck on what the tool added.
More conversation, less progress
Iterating means being able to try, get a response, and adjust course. A person can discover what they want while talking.
When every adjustment becomes a new demand to justify the request, that possibility is lost. You have to convince the tool to go back to the starting point.
“That isn’t what I asked for” should allow a change of course. If it becomes just one more sentence appended to the history, the error gains company instead of being corrected.
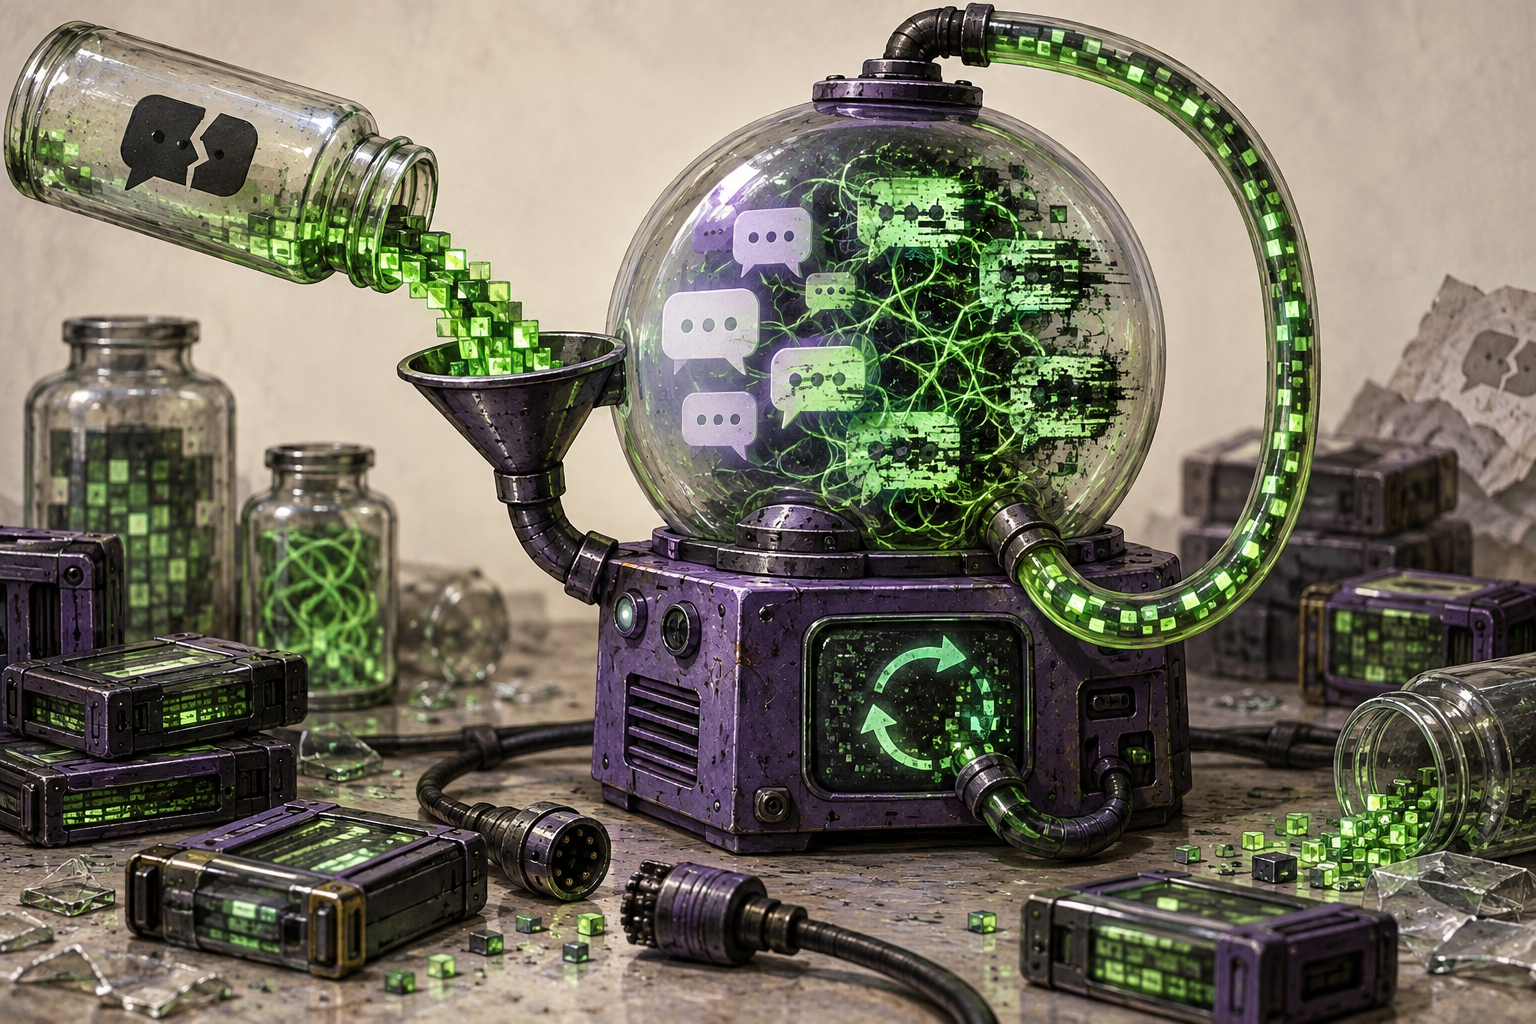
The machine in the image receives contaminated data and circulates it again. That is the metaphor: context produced by the tool itself comes back to feed its next responses.
The research found a closely related problem
Laban and colleagues studied tasks spread across multiple rounds of conversation. In the experiments, the models tested often made early assumptions and leaned too heavily on the solutions initially generated, with difficulty getting back on course. It is evidence of a conversational reliability problem; it does not show that every question is harmful, nor does it exactly reproduce the scene in this post. Read LLMs Get Lost In Multi-Turn Conversation.
The result helps formulate a simple requirement: a conversational tool needs to be able to revise what it itself presumed.
What happens technically, in plain language
The model does not respond only to your last sentence. In a chat, it receives a context: instructions, previous messages, and other materials the application may include. Think of this as the worktable available for drafting the next response.
That text is split into small pieces called tokens. In Transformer-based models, self-attention relates those pieces and combines information among them. In this way, earlier passages can influence what will be generated. Attention is a calculation; it is not an automatic evaluation of truth. The mechanism was presented in Attention Is All You Need.
Here is the point: a wrong answer from the model itself can come back as part of the context of the next turn. It ends up on the table alongside the request and your correction.
Imagine you say “I want to explore possibilities” and the model replies “let’s prepare the launch.” If that interpretation keeps guiding the next responses, the conversation starts revolving around a launch you did not request.
The error went out in the response and came back as input information. Repeated or developed, it can sustain new assumptions and make a change of course harder. This does not mean that each repetition necessarily increases its attention weight.
It is in this sense that we use “context poisoning”: misleading information produced during the conversation harms the following responses and stalls iteration. It does not imply a change to the parameters learned in training; the problem described lies in the use of context during generation.
A conversation makes it possible to observe this deviation, but not to measure the internal attention weights or prove its exact cause. “Attention points” is our informal expression for references that keep pulling the conversation in the wrong direction.
A collaborative tool should distinguish what you asked for, what it inferred, and what has already been corrected. And allow a correction to actually change the next response.
If you have already spent more time correcting the conversation than carrying out your task, tell us through the post’s private story form. Which interpretation kept coming back, even after you explained?